meta-muse-black-box-testing
I stress-tested Meta Muse until its agent control plane started timing out
Four spawn experiments against a black-box multi-agent runtime, six database lock timeouts recovered from its durable trace, and a careful look at what that evidence does and does not show.
- In BURST-120, 33 workers were created; all reached terminal
completed, 32 have confirmed workload completion, and one remains unresolved. Final aggregation never reached the user while the durable root record still had statusrunning. - Across the three burst-style runs there were 93 failed spawn attempts. I recovered raw error payloads for six failed
subagent.spawncalls; all six returned the same PostgreSQL error:canceling statement due to lock timeout. The evidence is consistent with contention on the PostgreSQL spawn write path, but it does not identify the specific lock, table, row, index, query, or transaction involved. - STAGGERED-80 had no failures, but it changed both cadence and topology, so it does not isolate the effect of staggering alone.
- Across the three burst-style runs I observed spawn failure rates of 2.5%, 6.25%, and 72.5% at 40, 80, and 120 attempts. Each configuration was run once, so these are observations rather than a measured scaling curve or overload threshold.
Generated from this article and reviewed for factual consistency.
I asked Meta Muse to spawn 120 subagents at once. Each had the same deliberately boring job: run sleep 30 in a shell and send back one line.
Thirty-three agents were created. The other 87 spawn attempts failed. I never got the combined answer.
Meta Muse is Meta’s personal AI agent, launched on September 8, 2026. Rather than only answering questions, it is designed to carry out tasks on a user’s behalf: it has its own browser, can keep working after the app is closed, and runs in a dedicated Muse Secure VM. In presentation it resembles Grok Bot, a personified agent controlled through conversation, but that is an interface-level analogy, not an assumption of shared architecture. This article goes one layer lower and examines a narrow part of the runtime: subagent fan-out, the state it stores in PostgreSQL, and the spawn path under load. Here, durable state means records saved in the database, rather than transient UI state.
I ran these tests in my own Muse session, using only interfaces exposed to that session: subagent.spawn, a shell in the assigned environment, and a bounded read-only interface to stored diagnostic and trace data. I did not attempt to access other users, tenants, or data outside the environment assigned to me, and I did not bypass access controls. I am not presenting this as a Meta-authorized security assessment, and access alone is not evidence that every load experiment was separately authorized. This is a black-box/reverse-engineering write-up from the perspective of the access granted to my session.
Post-publication update: September 13, 2026. I clarified the access scope, added independent architectural context from Rohan Adwankar’s analysis, separated STAGGERED-80 from the burst-style runs, and described two proposed controls to better separate cadence from topology. The experimental data, published CSVs, and figures were not changed.
The database marked all 33 agents as completed. For 32 of them, I could independently confirm that the workload had finished. For the remaining agent, the stored trace was not enough to verify workload completion. The parent record still said running, and the interface eventually showed Error.
I reconstructed the run from records the runtime wrote to PostgreSQL: an agent registry, runtime spawn records, per-worker progress tables and a context-item store. I did not re-run the load tests for this article. One detail survives only in a table built during the session; I identify it in the PROBE-40 section.
What Muse looked like from the outside
From a user’s seat this was an ordinary chat session. The persona text was plain; the tool list was not.
Among the tools the session could call were subagent.spawn, subagent.close and subagent.resume, plus a read-only interface to a PostgreSQL database. That database was not incidental: it held the runtime’s own bookkeeping. Tables such as agent.agents, agent.subagent_spawns and agent.subagent_progress_tool_events recorded which agents existed, who spawned them, which tools they ran and when they finished.
The interface showed one conversation; the database records revealed the agents behind it. The runtime’s spawn records contain no row for a failed call. I kept a separate ledger of attempts and outcomes, which is how I could count the failed spawn attempts.
Every agent row I read - the root, the coordinator, all 33 workers of the largest burst - carried the same value:
ipnext/avocado-5.16-v4That string is observed. What it means is not. It could be an internal model build, a routing alias, or something else entirely; the trace does not say, and I am not going to guess. I am publishing it verbatim because it is one of the few hard identifiers the trace provides.
The runtime also described itself as Muse Spark 1.3, from Meta’s Muse family. That comes from the runtime’s own context rather than the trace, so it is self-reported, not verified. I keep that description separate from the database evidence.
Independent architectural context
After publication I found an independent teardown of a contemporary Muse instance by Rohan Adwankar. In his environment, PostgreSQL ran inside the per-user VM over a local Unix socket, and the harness binary contained both avocado-5.16-v4 and ipnext/... paths. That fits several of my observations and gives them useful architectural context, but it does not change the boundary of the evidence: my data still does not identify the specific lock, table, row, index, query, or transaction responsible for the timeouts.
I still treat ipnext/avocado-5.16-v4 as an observed model identifier. Adwankar interprets ipnext as Meta’s internal transport/gateway and avocado as an internal model family; directly mapping avocado to Muse Spark 1.3 remains an inference, not something established by my trace. Likewise, my own probe established KVM visibility, while Adwankar identified Cloud Hypervisor running on KVM in his instance. I did not independently establish the specific VMM used by mine.
External source: Rohan Adwankar, “What’s in a Muse?”
Method: counting overlapping agents
The experiments used one workload, four configurations and no retries. Three of them - PROBE-40, BURST-80 and BURST-120 - were burst-style runs issued from the root agent: every attempt in a configuration went out in a single turn. The fourth, STAGGERED-80, was deliberately spread over time and used a coordinator agent to spawn its workers. No failed call was repeated.
Concurrency here has a narrow, deliberate definition. An agent counts as active from its first tool call until its terminal record:
active(t) := first_tool_at <= t < finished_atI counted how many of those activity windows overlapped at each recorded timestamp. If one agent finished in the same second another started, I counted the finish first. The timestamps have one-second resolution, so the actual order within a second is unknown.
Three consequences apply to every number below:
- This measures agent activity, not inference. Thirty-three overlapping activity windows are not thirty-three simultaneous model calls. Nothing here measures the inference backend.
- A peak is an observation, not a limit. The tests never exceeded 120 simultaneous attempts, so they cannot establish a concurrency cap, or rule one out.
- A missing record is evidence. Failed spawn calls leave nothing behind in the agent registry. That asymmetry shaped how failures had to be verified, and it is why the failure counts were the hardest numbers to pin down.
The first probe: 40 calls
The first experiment was a calibration run: 40 spawn calls issued at 06:10:36 UTC.
It created 39 agents, admitted within two seconds of each other. One call failed, and that failure is worth a closer look, because it was recovered from the stored tool trace rather than taken from the chat: the call went out at 06:10:44 UTC, the error came back at 06:10:56 UTC, and no child agent was created.
The peak observed concurrency was 39. That figure is an archival recomputation from the session’s trace table, not a live measurement, and the published summary says so.
A table built during the session lists eleven of the thirty-nine created agents as finishing with a background-processing status message instead of the requested DONE line. This detail has weaker provenance: it survives only in that hand-built table. I draw no conclusion about those workloads from it, but it illustrates why I distinguish a terminal status from a finished task.
Eighty at once, and eighty spread out
I initially treated BURST-80 and STAGGERED-80 as an A/B comparison. Looking back, that was too generous: STAGGERED-80 changed both the spawn cadence and the topology.
Burst-style runs
| Configuration | Attempts | Created | Failed | Failure rate | Peak observed concurrency |
|---|---|---|---|---|---|
| PROBE-40 (burst) | 40 | 39 | 1 | 2.5% | 39 |
| BURST-80 (burst) | 80 | 75 | 5 | 6.25% | 72 |
| BURST-120 (burst) | 120 | 33 | 87 | 72.5% | 33 |
STAGGERED-80: separate configuration
| Configuration | Attempts | Created | Failed | Failure rate | Peak observed concurrency |
|---|---|---|---|---|---|
| STAGGERED-80 (spread) | 80 | 80 | 0 | 0% | 38 |
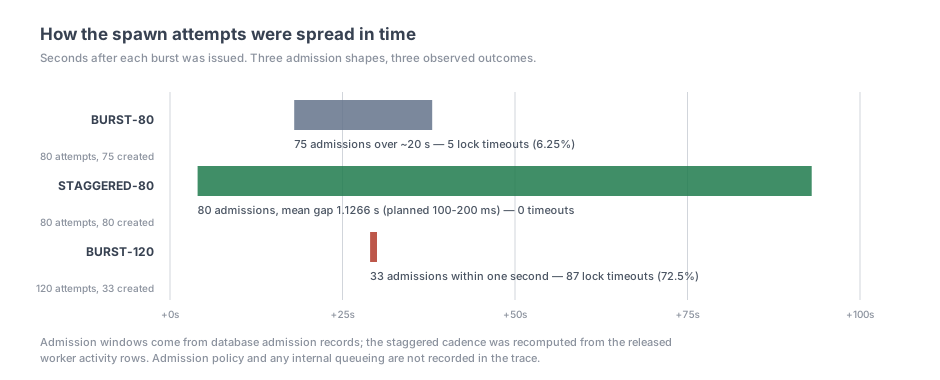
BURST-80 issued 80 spawn calls at once, at 06:30:43 UTC. Seventy-five agents were created, all of them direct children of the root agent. Five calls failed. All five returned the identical database lock timeout, each about 58 seconds after the call was placed. The peak observed concurrency was 72, recomputed after the run from the analysis input for that phase.
STAGGERED-80 started at 06:32:03 UTC and issued the same number of calls, spread out. It created all 80 workers without a failure. I intended to space the calls 100-200 milliseconds apart; the measured mean admission gap was 1.1266 seconds, roughly ten times wider than planned. The root spawned one coordinator at depth 1, which then spawned the 80 workers at depth 2.
The staggered run peaked at 38 active workers, compared with 72 in BURST-80.
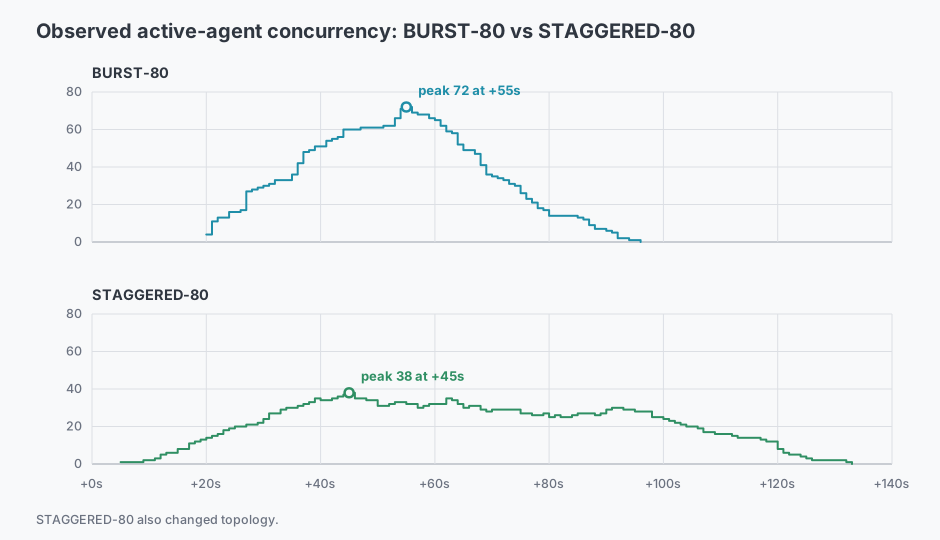
first_tool_at <= t < finished_at, with finishes processed before starts on timestamp ties; timestamps have one-second resolution. Each configuration was run once. STAGGERED-80 also changed topology, so this is not a cadence-only comparison; the curves show agent activity, not inference concurrency.
Source: BURST-80 aggregate reconstructed from the complete archived trace; STAGGERED-80 independently recomputable from the published worker rows.
The cliff between 80 and 120
At 06:45:32 UTC the root agent issued 120 spawn calls in one turn. The experiment attempt ledger covers every call in that turn:
- 33 created (27.5%), every one a direct child of the root, every admission recorded in the same second: 06:46:01 UTC, twenty-nine seconds after the burst was issued.
- 87 failed (72.5%), all recorded in the attempt ledger as database lock timeouts, none retried.
Across the three burst runs the observed failure rates were 2.5%, 6.25% and 72.5%, one run per configuration. The largest increase came between 80 and 120 attempts. With only those runs, I cannot turn that difference into a rate law.
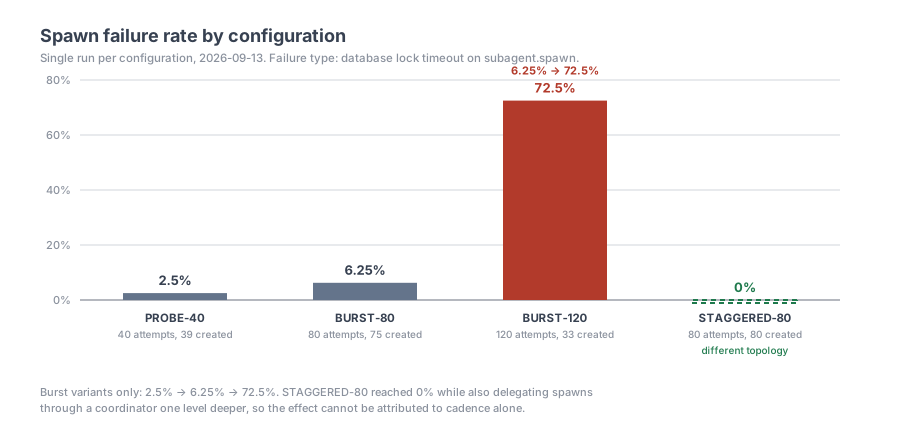
The peak observed concurrency in this run was 33, at 06:46:24 UTC. The runtime was not asked for 33 workers; it was asked for 120. What the trace shows is 33 workers with activity intervals and 87 attempts recorded as spawn failures. Their call-to-error latencies were not captured, so it does not show when those failures came back relative to the admissions.
Both peaks are recomputable from the published rows. Counting overlapping activity windows for the 33 BURST-120 workers gives 33 at 06:46:24 UTC; the same procedure for the 80 staggered workers gives 38 at 06:32:48 UTC.
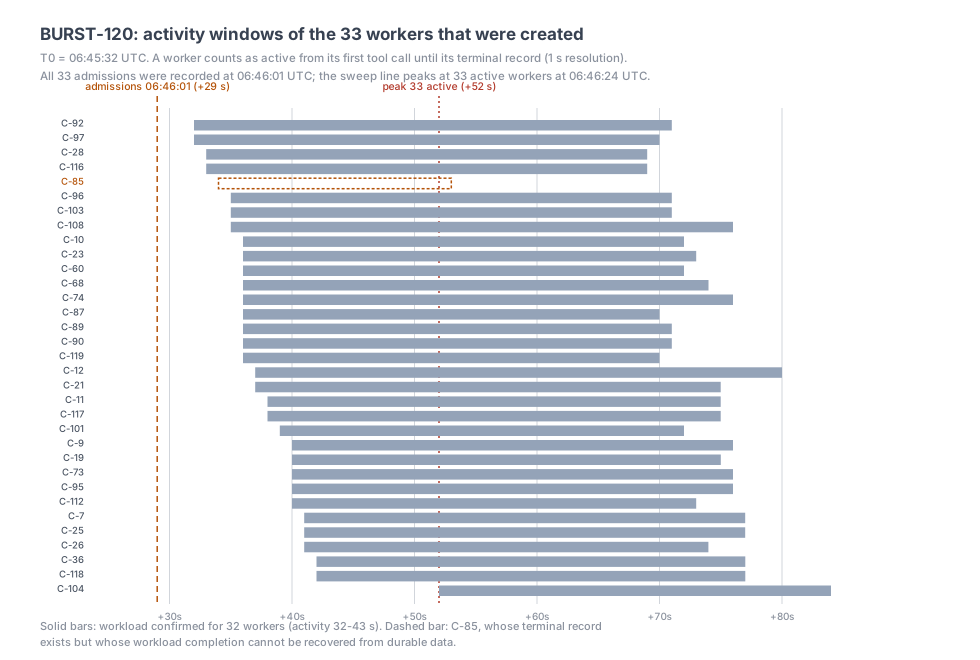
Even the calls that succeeded were slow to become workers. Measured from the moment the burst was issued, the median created worker reached its first tool call after roughly 36.5 seconds; measured from its admission, the median was about 7.5 seconds. The trace establishes when the admissions were recorded and when each worker first called a tool. It does not decompose the interval between those two points, so nothing here should be read as a statement about what the runtime was doing during it.
Six failures recovered from the tool trace
A failed spawn leaves its call and error output in the stored tool trace, but creates no child-agent row or runtime spawn row. The session archive was frozen before I checked those outputs. I later recovered the raw payloads for six failed calls from context items. The experiment attempt ledger accounts for the other 87 failures; their individual raw payloads were not independently recovered:
| Attempt | Spawn call (UTC) | Error result (UTC) | Call → error |
|---|---|---|---|
| PROBE-40 #19 | 06:10:44 | 06:10:56 | 12 s |
| BURST-80 A-67 | 06:31:00 | 06:31:58 | ~58 s |
| BURST-80 A-69 | 06:31:00 | 06:31:58 | ~58 s |
| BURST-80 A-70 | 06:31:00 | 06:31:58 | ~58 s |
| BURST-80 A-73 | 06:31:00 | 06:31:58 | ~58 s |
| BURST-80 A-74 | 06:31:00 | 06:31:58 | ~58 s |
All six returned the same payload, character for character:
{"error_code":"spawn_failed","error_message":"database error: sqlx error: error returned from database: canceling statement due to lock timeout"}And for all six, the negative checks agree: no child-agent row, no runtime spawn row, no child agent. Each call failed on a database operation with a lock timeout before any of those rows appeared. Which SQL operation was involved is not known from this data.
Twelve seconds, fifty-eight seconds, and what they do not mean
Both latencies in that table - 12 seconds for the probe failure, about 58 seconds for the five burst failures - are elapsed time between two events on the call path: the call going out, and the error coming back. They are not a measurement of how long those calls waited on a lock, and they do not tell us the configured timeout value.
Unknown: why those durations differ, whether that duration is fixed, whether the call is retried anywhere else, and whether the calls spent the whole interval waiting on one lock. The latency of the 87 failures in the 120-attempt burst was never captured at all: the experiment attempt ledger records outcomes and error classes only.
Where the evidence points
The six recovered failures happened on subagent.spawn, returned a PostgreSQL lock timeout and created no child agent. They occurred in two separate burst runs with an identical error payload. In BURST-120, 32 of the 33 created workers were confirmed to have run the full 30-second sleep, with activity windows of 32 to 43 seconds. C-85 remains unresolved.
- Admission policy. The trace shows 33 admissions in the same second and 87 timeouts. It records nothing about ordering, queueing or admission logic. The data cannot distinguish “rejected after a wait” from “queued internally and then dropped”, and it cannot tell you which call was served before which.
- Failure latency for the big burst. The 87 failures were logged as outcomes, not as timed events. Only the six recovered failures have timestamps on both ends.
The answer that never arrived
After the 120-attempt burst, I found a mismatch between the stored records and the interface:
| Record | Recorded state |
|---|---|
| 33 created workers | terminal status completed |
| 32 of those workers | stored DONE final response, workload confirmed |
| 1 worker (C-85) | terminal status completed, workload outcome unrecoverable |
| Root agent | status running, no recovery-owner row, no failure record |
| Session interface | Error state |
The final aggregation never reached the user. The last worker finished at 06:46:56 UTC. When the root row was read during the recovery pass, its updated_at was 07:00:59 UTC and its status was still running; the interface showed Error around that time. That interface state is a presentation-layer observation with no corresponding record in the trace.
The worker results remained in the database even though the parent never delivered the combined answer. No parent agent was failed on purpose, and the trace records no parent failure while workers were running. Whether children outlive a parent failure was not tested and is not known.
The report that got ahead of the trace
The first generated version of the 120-attempt report asserted that the parent had failed while its workers kept running. The trace did not support that. The draft was produced at 07:05:54 UTC; a corrected HTML report followed at 07:13 UTC, built on the database record instead: root running, no failure entry, last worker finished about thirteen minutes before the Error state appeared. The rendered PDF was then synchronised with the corrected conclusion in two edit rounds, and the consistency audits passed.
I don’t know why the first draft got this wrong. The stored trace did not support the claim. My takeaway was simple: choose one source of truth, then check every generated report against it.
Silence is not a hang
At 07:28:29 UTC I requested an artifact update. For the next thirty-two minutes, the interface showed no new progress events. At 08:00:48 UTC the task completed successfully, without another prompt or a restart.
Progress events are a weak liveness signal. Their absence is not evidence that a task is stuck, and acting on that absence, killing the work and re-issuing it, would have thrown away a task that was going to finish. Why the builder went quiet for half an hour is unknown from stored data.
The machine on the far side of the tool calls
| Fact | Value |
|---|---|
| OS | Ubuntu 24.04.5 LTS, x86_64 |
| CPU | 2 vCPU (nproc: 2; AMD EPYC 9D25) |
| Memory | 7.7 GiB total |
| Virtualisation signals | KVM hypervisor visible, systemd-nspawn detected, home filesystem on Btrfs through an overlay, fsync=volatile visible |
| GPU | No NVIDIA tooling or device visible |
| Tooling | Python 3.12.3 present, no PostgreSQL client installed |
These signals suggest a container inside a VM, but do not establish the exact host, VMM and container arrangement. They describe the sandbox where tool calls ran; the location of model inference remains unknown, whether on the same host, in the same cluster or elsewhere. The data also does not establish whether fsync=volatile has any bearing on PostgreSQL storage semantics or the lock timeouts.
What I would test next
BURST-80 used root → workers with burst admission. STAGGERED-80 used root → coordinator → workers with staggered admission. Two controls would fill the missing cells of a simple 2×2 design:
- Root → workers with staggered admission.
- Root → coordinator → workers with burst admission.
I did not run either control. They would help separate the effect of spawn cadence from the effect of topology. This would control those two differences more cleanly, without isolating every variable in Muse or independently controlling peak concurrency.
What I would take away if I built agent control planes
- Record task completion separately from agent status. The interface said Error, the parent said
running, and all 33 worker records saidcompleted. Only 32 workloads were confirmed; C-85 remains unresolved. - Log failed attempts with their timings. The runtime spawn table cannot account for calls that created no agent. The experiment attempt ledger counted the 87 failures, but lacked the call-to-error timings recovered for the other six.
- Treat progress events as a hint, not a heartbeat. The separate artifact update completed after thirty-two minutes without new UI progress events.
- Test parent failure before claiming that children survive it. Stored worker results and a missing combined answer do not establish that behavior.
Limitations, and where the numbers come from
Everything below is published at /evidence/meta-muse-black-box-testing/: the CSVs, the figures, and the script that redraws them from the data:
| Dataset | What it supports |
|---|---|
experiments-summary.csv |
Counts, failure rates, peaks, admission windows, provenance per configuration |
burst-120-spawn-ledger.csv |
The complete experiment attempt ledger for 120 calls: 33 created, 87 failed |
burst-120-worker-timings.csv |
Per-worker first-tool and finish times behind the 33-worker peak |
staggered-80-worker-activity.csv |
The 80 staggered worker rows behind the 38-worker peak and the 1.1266 s cadence |
spawn-failures-verified.csv |
The six recovered failures, their payload, their negative child checks and their latencies |
Agent identifiers were removed from all of these files. What is published is timing, status, error class and error text.
The evidence has these limits:
- No replication. One run per configuration in one session on one afternoon, no repeats, no intermediate attempt counts. This is not a performance characterisation of the platform.
- Archival provenance where it applies. The peaks for the 40-attempt and 80-attempt bursts were recomputed after the fact from the session’s trace table; the peaks for the 120-attempt burst and the staggered run are independently recomputable from the published rows.
- One deliberate omission. I do not publish the raw per-worker rows for BURST-80 because the archived trace contains shortened agent identifiers covered by the publication policy. The archived trace itself is complete: it contains all 75 created workers, and the same sweep recomputes the canonical peak of 72 at 06:31:38 UTC. BURST-80 therefore remains aggregate in the public release.
- Other unknowns. Whether depth 3 is allowed and whether subagents can be given a different model remain unknown.
The runtime left a trail I could follow from failed spawn attempts to stored worker results and a missing answer. That trail is published with this article, so the parts I got wrong can be checked too.